Near Criticality

Notes by Zhongwei Wang on RL, AI, physics and complex systems

A Mental Model to Unify RL Losses

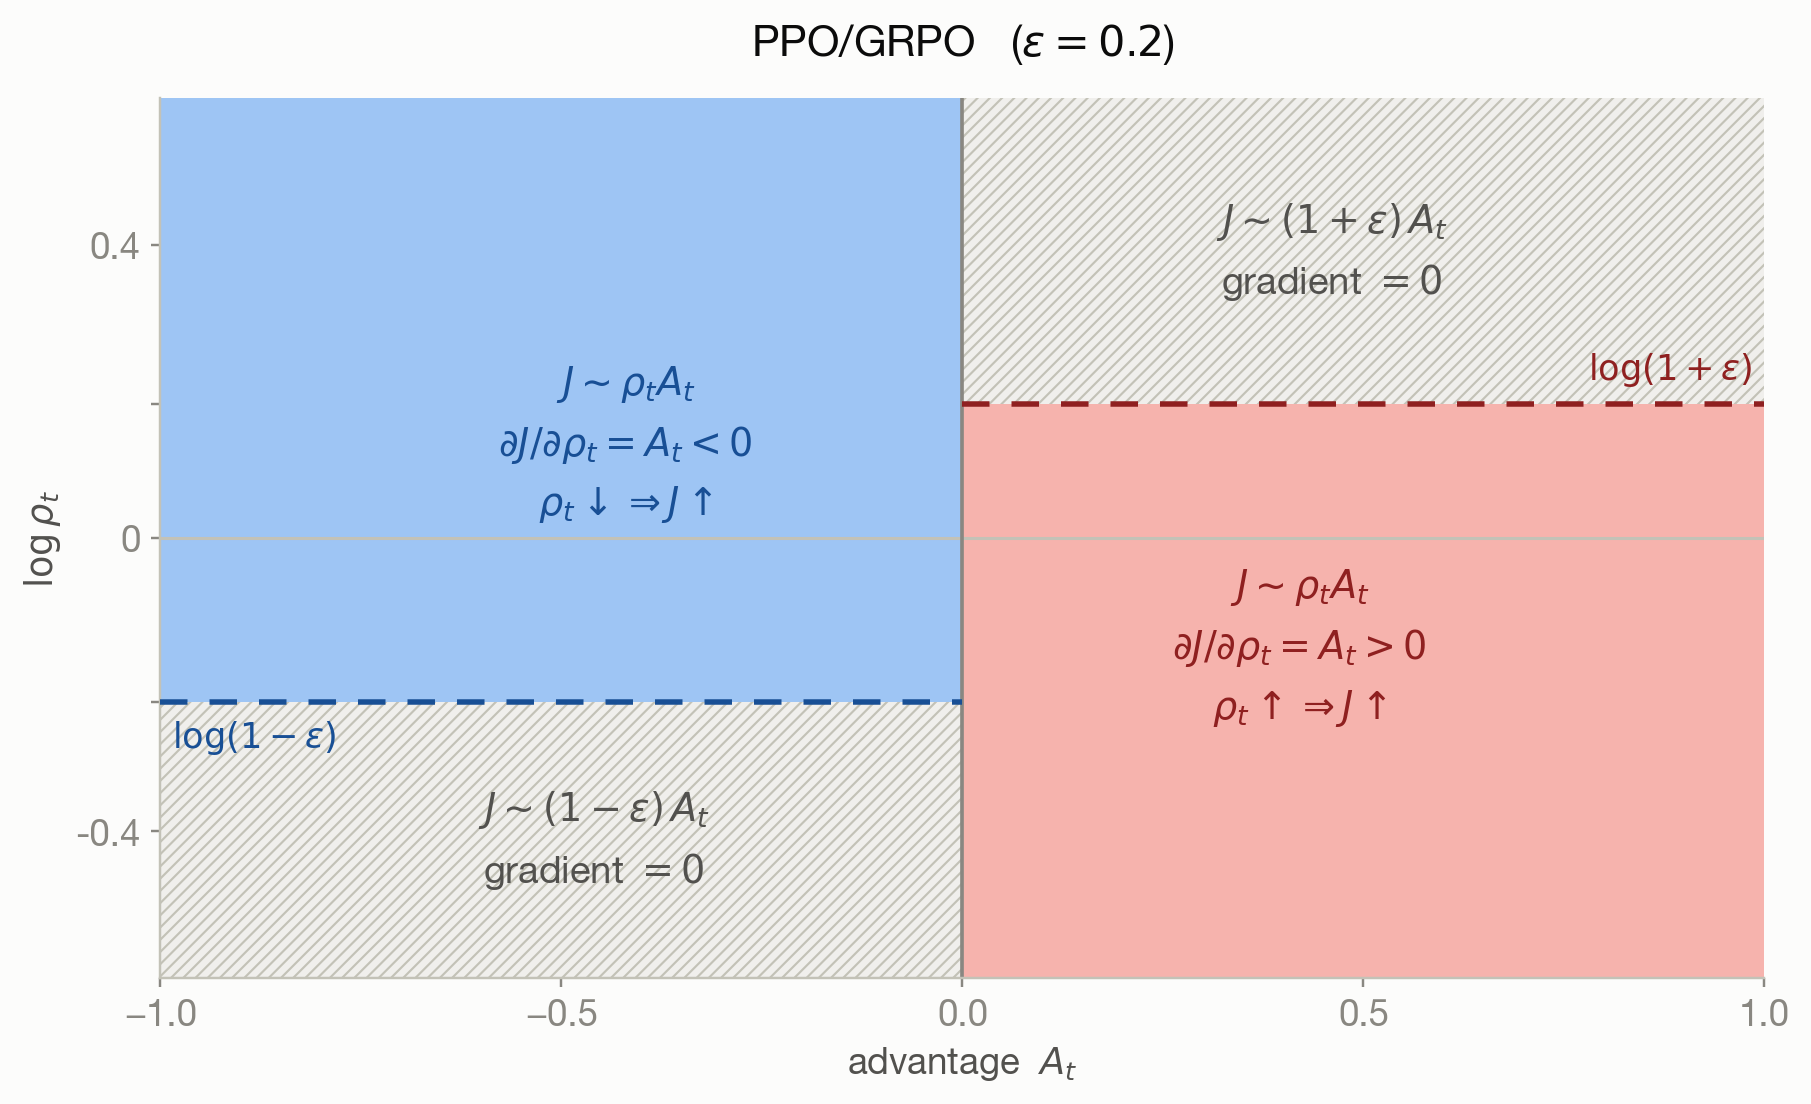
The diagram that compares PPO/GRPO, DAPO, GSPO, SAO, SAPO...

Inspired by the Feynman technique, I’ll explain some famous LLM RL losses as simply as I can—starting with PPO and GRPO, then recent variants DAPO, GSPO, SAO, and...

Read
A Statistical Mechanics View of KL-Regularized RL

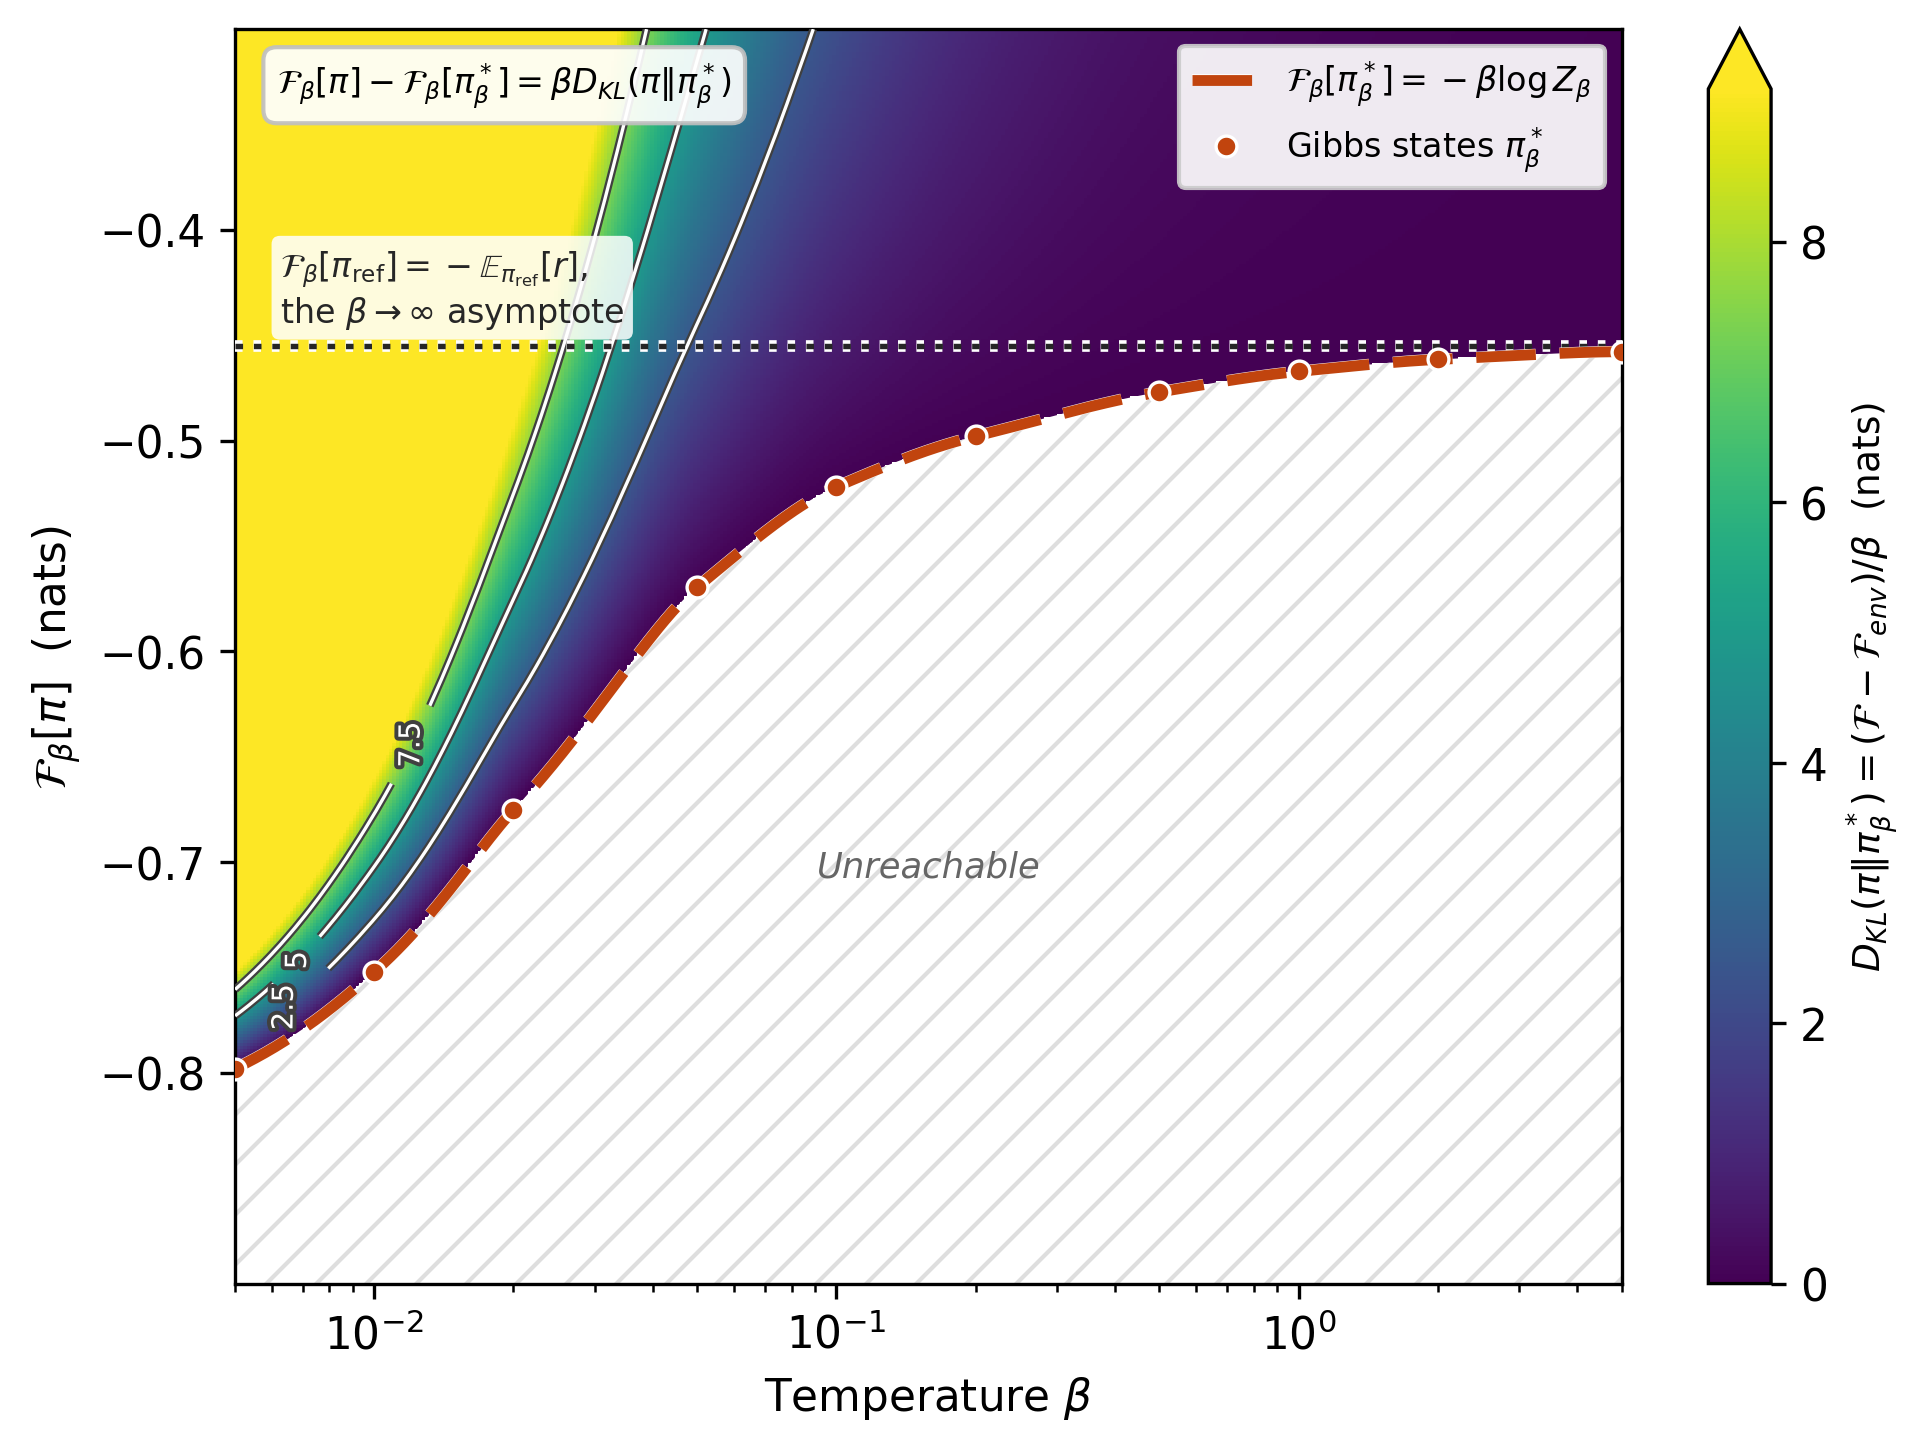
The math behind DPO, PPO, and the GRPO family — and whether training reaches the Gibbs minimum

Preference post-training is often formulated as KL-regularized reward maximization: increase expected reward while staying close to a reference policy. Its optimu...

Read